Our Data Sources
AI in These Studies says every language claim on this site has to "resolve to a real entry in a real dataset." This page names those datasets: where each one comes from, what its licence lets a study do with it, and how a study reaches it.
The machine-readable record behind this page is
references/sources.toml.
It records where every source lives, which licence tier it sits in, how much of it may be quoted,
and a short profile of what it is good and poor at. The build scripts and the query tools all read
it, so this page and the tools agree.
Four other pages take up neighbouring questions, and Getting Started shows how to build this data into a workbench of your own:
- Public Data Sources surveys the open Bible data that exists, including sources considered and turned down.
- Bible Translations & Source Texts weighs what each text is worth as a witness.
- Reading the Original-Language Data explains the data's own vocabulary: lemma, parsing, semantic domain, MACULA.
- Patristic Sources covers the church fathers.
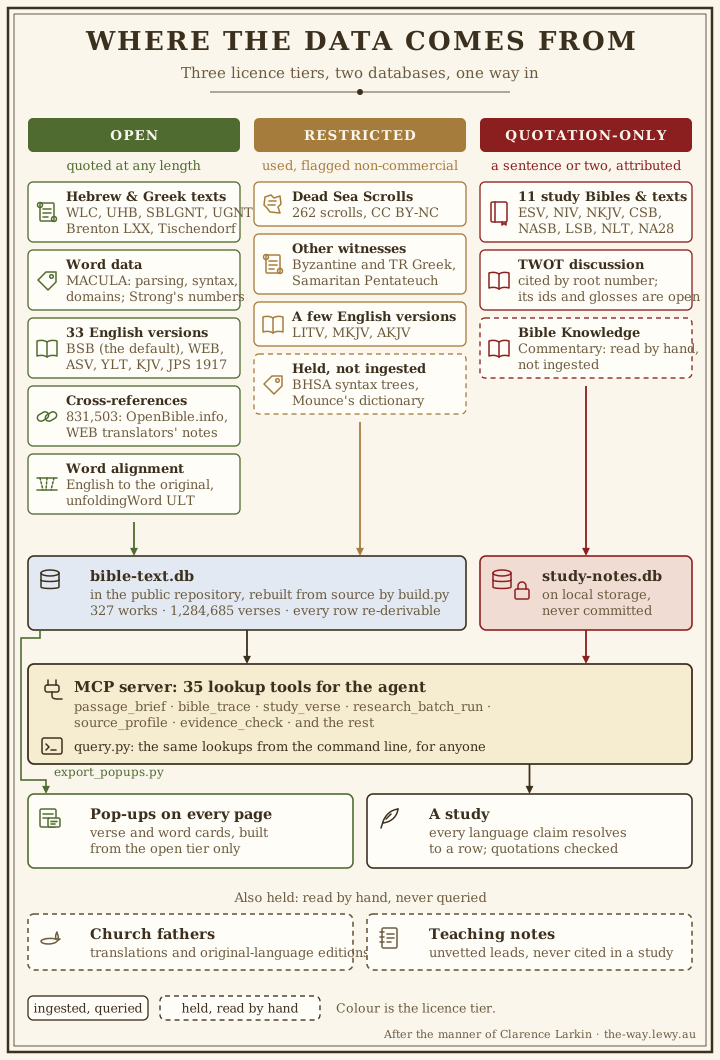
Three tiers, one rule
Every source falls into one of three licence tiers, and the tier decides how a study may use it:
- Open: public domain, or a permissive licence (CC BY, CC BY-SA, CC0). Cited and quoted at any length.
- Restricted, non-commercial: licensed for non-commercial use. This site earns nothing, so it uses them now, and each is flagged by name in case that ever changes.
- Quotation-only: commercially published, copyrighted text or commentary. Named, cited, and quoted a sentence or two at a time with attribution. It is never reproduced at length or stored in the public repository.
A fourth label, unknown, covers six works whose upstream licence metadata is missing or does not fit a Bible text, such as two KJV editions their source tags with a software licence (GPL). Unknown is treated as not quotable until the licence is settled. The Pure Cambridge Edition of the KJV is in the open tier.
What each tier is for
Open data carries the word studies. The Hebrew and Greek texts, morphology, lemmas, Strong's numbers, Louw-Nida and SDBH semantic domains, clause-level syntax and coreference, cross-references, and 33 English versions are all open. The BSB is the default English text in the data and the pop-ups, the ASV and KJV are there for comparison, and Young's Literal is a word-for-word cross-check that a study never quotes as a verse's meaning. Studies themselves quote the ESV. Bible Translations & Source Texts carries a per-edition table for every English translation, Hebrew witness and Greek New Testament here.
Restricted data fills specific gaps. The Dead Sea Scrolls are by far the largest part, 262 scrolls under CC BY-NC, which let a study see where a manuscript a thousand years older than the Masoretic Text reads differently. The Byzantine and Textus Receptus Greek texts and the Samaritan Pentateuch are independent lines of the text, and a few English versions sit here too. BHSA, a deep Hebrew syntax database, is licence-checked and held but not yet ingested. MACULA already gives subject, role, construct state and coreference for both testaments, so BHSA waits for an argument that needs its full clause hierarchy.
Quotation-only data checks the work. Commentaries come last: they test a reading already reached from the text and never form it. Because this tier carries no right to redistribute, it is built and stored on local storage outside the public repository, so it cannot be published by accident. It holds eleven works: the ESV Study Bible, the NIV Biblical Theology and NIV Cultural Backgrounds Study Bibles, the NKJV Cultural Backgrounds Study Bible, the CSB Ancient Faith Study Bible, the NLT Life Application and NLT Christian Basics Bibles, the NASB 1995 and 2020, the LSB 2021, and the NA28 Greek New Testament. These are also the only copies here of the ESV, NIV, NKJV, CSB, NASB and LSB verse text, which is why every ESV quotation on the site is checked against them. The Bible Knowledge Commentary (Walvoord and Zuck) is held as an ebook and read by hand. It is the check to run when a study says what the dispensational reading holds.
TWOT: one source, split across two tiers
The Theological Wordbook of the Old Testament splits across two tiers. Its bare facts, the
Strong's number that points to a TWOT root with its lemma and one-line gloss, are committed as a
plain JSON map (references/build/twot/twot_strongs_map.json) and used freely. Its discussion
prose, the paragraphs of argument behind each root, is quotation-only: cited by root number and
gloss, and quoted a sentence at a time with attribution.
What sits outside both databases
The early church fathers are kept as plain text on the same local storage, because they are read and never queried. There are nine works: two 19th-century English translation sets for finding a passage, and seven original-language critical editions in Greek and Latin for anything that turns on a father's actual words. Which of the two a citation rests on decides what it can support. Patristic Sources sets out the difference, including a case where this site got it wrong and retracted.
Raw teaching notes in references/biblefacts/ are transcripts and summaries of third-party
teaching. They sit outside every tier: unvetted leads to chase down in a primary source, never cited
in a study.
Six sources are held but not ingested: BHSA and Mounce's Greek dictionary (restricted), and four open collections, the Hebrew lexicon, the STEPBible data, the Strong's dictionaries and the English deuterocanonical texts. The query tools cannot see them. The Greek of those books is queryable: Brenton's Septuagint carries fourteen of them, and Swete's supplies the Odes, the Psalms of Solomon and Psalm 151. The source catalogue lists them by name, so a text is never reported as missing while it sits on disk unread.
Keeping our own copies
A claim stays checkable only while the source under it can still be reached. So this project keeps its own copy of each open source it uses, pinned to an exact version. If a dataset changes upstream, the studies do not change with it.
The four unfoldingWord sources are the exception so far: the Hebrew Bible, Greek New Testament, Literal Text and Hebrew Grammar. They are pinned to an exact version, but the copy is still the publisher's own, on their server. Taking our own copies is on the list.
Those four also carry a share-alike licence (CC BY-SA). That places no limit on quoting them. It would matter only if this site published a dataset built from them.
What each of the four does here
They are working instruments, and no study quotes from them; studies quote the ESV by default. Each answers a question nothing else here can:
| Source | What it answers | Where it shows up |
|---|---|---|
| ULT, Literal Text | Which original word is this English word translating? Every word carries an alignment naming the Hebrew or Greek behind it | the 475,036 rows in word_alignment, and 326 translator footnotes |
| UHB, Hebrew Bible | What did the Masoretes say to read instead? The text the ULT's Old Testament alignment resolves against | 949 footnotes, 930 of them Qere readings |
| UGNT, Greek New Testament | Does a second Greek edition read this differently? Derived from Alan Bunning's Heuristic Prototype, a text built by a computer-assisted method from the manuscripts | a fourth Greek witness in verses, and 22 notes on disputed passages |
| UHG, Hebrew Grammar | What does this grammatical form do, as distinct from what the word means | the 88 rows in grammar_articles |
unfoldingWord state two cautions themselves.
The UHB numbers verses the English way. It "uses the versification scheme of the ULT", which
they note "may make some resources that are keyed to the WLC more difficult to use with the Hebrew
text". So the UHB and the Westminster Leningrad Codex name different verses for the same reference
in about 1,500 places, mostly in Joel, 1 Chronicles, 1 Kings, Numbers, Job, Ezekiel and Malachi. The
UHB records its own Hebrew numbering verse by verse, and this site keeps that record as the
versification_map table. See versification.
Where the Masoretes left two readings, the UHB prints the written one: "in order to avoid subjectivity, the text of the UHB uses the Ketiv of the WLC", where the Westminster Leningrad Codex prints the one to be read aloud, the Qere. That one decision accounts for nearly all of the roughly 1.5% of verses where the two Hebrew texts differ. The 930 Qere readings are kept as notes on their verses, so both readings are always to hand. See Ketiv and Qere.
The UGNT also differs from this project's default Greek text in about one verse in six by raw count. Most of that is manuscript spelling, and a small part is a different reading.
The two databases, and what is in them
bible-text.db is rebuilt from scratch by
references/build/build.py
from the source collections above. Every row comes from a source file or is derived from them by
a committed script, and a re-run produces the same rows, so any claim resting on it can be
re-derived and checked.
| Table | Rows | What it holds |
|---|---|---|
works |
321 | one row per ingested text, with its licence and tier; every other table joins back to it |
verses |
1,222,501 | the text itself, every work, every verse |
morphology |
1,819,286 | per-word lemma, Strong's, parsing, and Louw-Nida/SDBH semantic domains, from MACULA |
cross_references |
831,290 | two inherited lists: OpenBible.info's crowd-voted set (830,866) and the WEB translators' own footnotes (424) |
word_alignment |
475,036 | which original word each English word renders, from unfoldingWord's ULT |
scripture_links |
2,304 | quotations and allusions this project detects itself from the texts |
dss_variants |
1,874 | where a Dead Sea Scroll reads something the Masoretic text does not |
literary_units |
1,181 | paragraph and pericope boundaries from the Masoretic markers |
versification_map |
2,033 | the Hebrew verse number for each verse the UHB numbers the English way, as the source states it |
notes |
1,297 | the translators' own footnotes: where they judged the text ambiguous, and what the alternative was |
grammar_articles |
88 | what a Hebrew form does, as distinct from what a word means |
study-notes.db is built by build_study_notes.py from the commercial study-Bible ebooks and kept
entirely outside this project's public repository, on local storage.
The scripts that clean and derive
| Script | What it does |
|---|---|
build.py |
Builds bible-text.db from the sources, and does the cleaning: collapsing upstream's duplicate verses, and stripping formatting symbols that had reached 47% of WEB verses and 24% of the Brenton Septuagint |
quotations.py |
Derives scripture_links: an n-gram index finds candidates, then Smith-Waterman local alignment scores them. Joining Hebrew morpheme separators, where splitting on them had found 12% of known quotations, raised that to 81%. Every threshold was set by measurement against the cross-reference lists |
versification.py |
Moves a reference between the Masoretic, Septuagint and English schemes. Hebrew Joel 3:1 is English Joel 2:28, and reading one under the other raises no error |
query.py |
The query layer over the finished database, with a command line |
mcp_server.py |
Exposes the same lookups, over both databases, as tools an AI agent can call |
export_popups.py |
Writes the verse and word pop-up data from the open tier only, since it ships to every reader's browser |
build_study_notes.py |
Builds the external study-notes.db |
study_gaps.py |
Reads a finished study and reports what connects to its passages that it never cites |
commentary_index.py, section_index.py |
Regenerate the automatic sections of committed pages from their frontmatter |
How a study reaches the data
Studies are written against these tables, through the same lookups anyone can run. The AI agent that drafts a study connects through an MCP server (Model Context Protocol, a standard way for an AI model to call tools). Its 33 tools wrap the query library; they add no second copy of the logic. Ask for a verse and get its text, its per-word parsing and its cross-references. Ask for a word and get every occurrence. Ask what an English word is translating and get the original behind it.
passage_brief is where work on a passage starts. One call returns the versification, the book
introduction, the text in each translation asked for, the interlinear, Hebrew roots, cross-references,
Dead Sea Scroll differences and study notes, in the order an exegesis works through them.
bible_trace takes a verse and returns everything the collection knows about its connections: what
it quotes, what quotes it, the words the two share, and how each link was established. Each link
arrives with its evidence, so a reader can judge it.
What a study checks, it records. A study's state file keeps each verified lookup with the answer it
must contain, and verify_claims.py --evidence replays them, so a quotation or a gloss checked once
can be checked again after any change to the data.
The rule for every tier
Whatever the tier, one rule governs every study: a language or textual claim has to resolve to an actual row in one of these two databases, checked when the study is written. That is what "checkable" means on the AI in These Studies page, and How This Site Is Built documents the tools for checking it yourself.
See also
- Bible Translations & Source Texts: the per-edition deep dive on every English translation, Hebrew witness and Greek New Testament text, including which are queryable
- Copyright & Scripture Permissions: the publishers' own required notices
- How This Site Is Built: the build pipeline and query tools
- references/README.md: the full developer-facing catalogue, with exact query patterns for every source above